Module A02 · concept player
Coalescing, with the stride in your hands
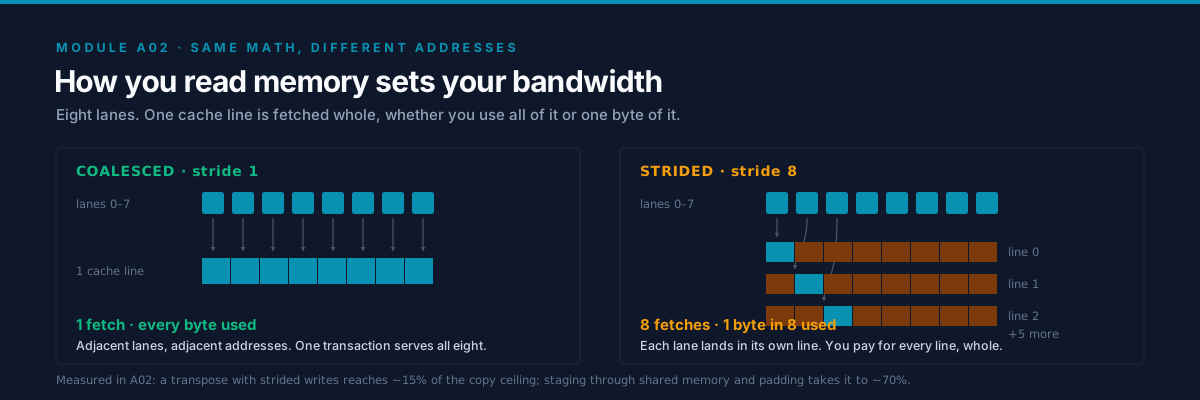
One wavefront, one instruction, the same arithmetic every time. The only thing you change is the distance between the addresses each lane asks for — and that alone decides how much bandwidth you get.
What the hardware fetches
bytes a lane asked for bytes fetched and discarded
These are counts, not measurements. A 128-byte line and 4-byte elements make lane
i touch line floor(i × stride / 32), and everything above follows
from that. Real hardware also has caches, coalescers and outstanding-request limits, so measured
bandwidth will not fall off as cleanly as 1/stride.
A02's
lab measures the real curve on your own GPU; a strided transpose there reaches about 15% of
the copy ceiling, and staging through shared memory takes it to about 70%.